AI is becoming ordinary. The evidence about its effects is still catching up
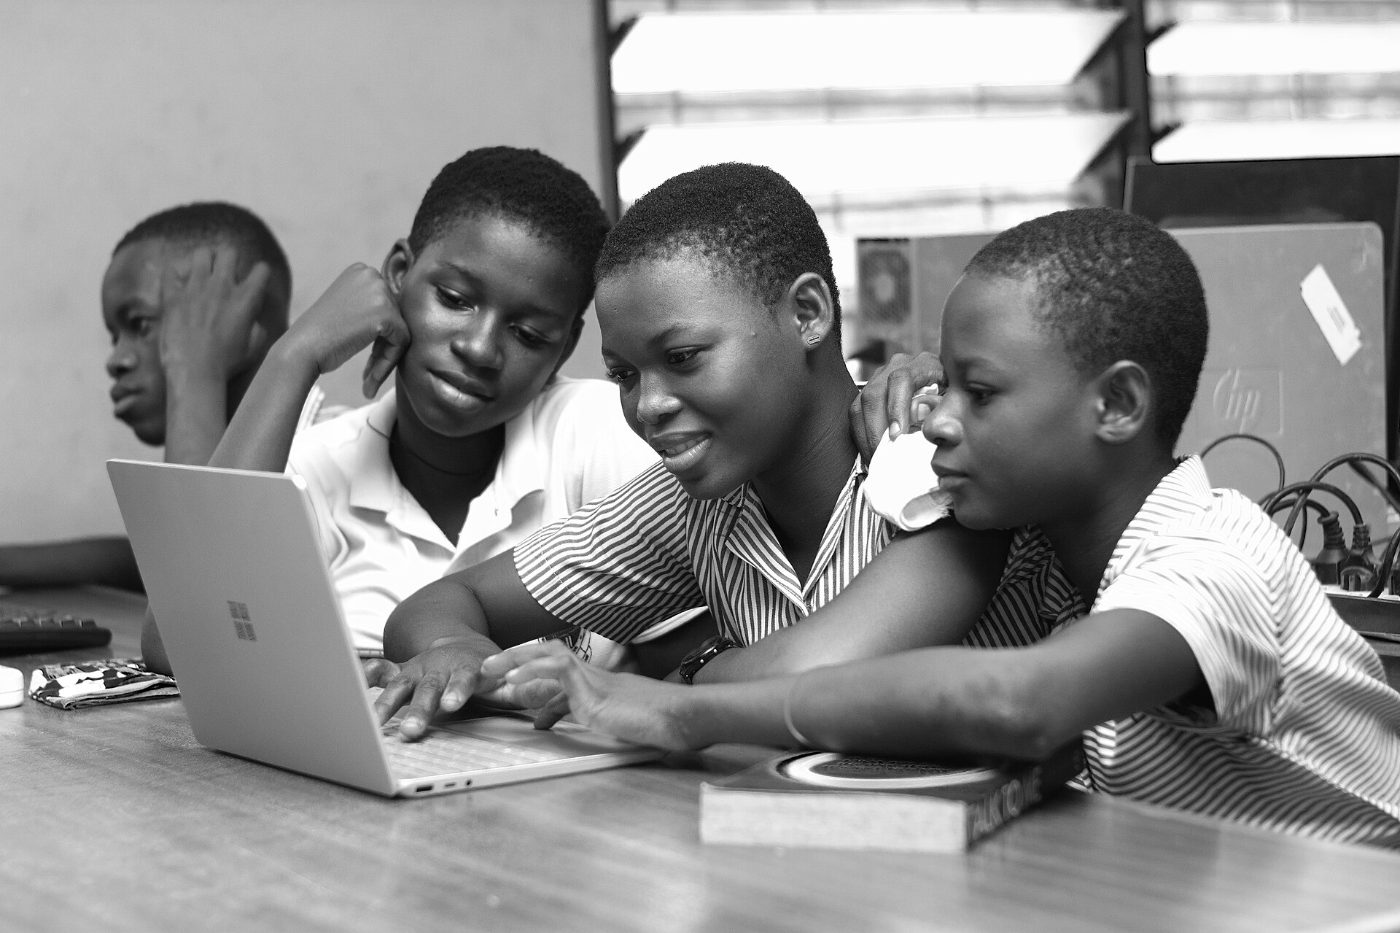
Photograph: Bright Kwame Ayisi / Wikimedia Commons, CC0.

Two students spend thirty minutes with the same AI model. One asks for the answer and copies it. The other attempts the problem first, asks for criticism, argues with the response and revises the work. A study that records both as thirty minutes of AI use has measured time well and behaviour badly.
I had those two students in mind while reading OpenAI’s call for research on AI and teen development. On 8 September 2026, the company announced $5 million for independent research on how generative AI affects people aged 13 to 17. The call asks about emotional development, relationships, patterns of use, safeguards, AI literacy and differences across social and cultural settings. Those are better questions than the one public debate keeps returning to, which is whether AI is good or bad for learning.
The funding source matters. A company developing the technology has an institutional interest in the evidence that grows up around it, which makes independence, disclosure, publication and replication important. The call requires conflict disclosures, lists independence and credibility among its review criteria and encourages public release of findings. Whether that proves enough will depend on what gets published, including results the funder would rather not see.
Early evidence needs the same care. A 2026 meta-analysis in Humanities and Social Sciences Communications reported generally positive pooled effects of generative-AI-supported approaches on outcomes including academic achievement, higher-order thinking and writing. It is a reasonable place to start. A pooled estimate, though, averages over many designs, and it cannot say which of my two students drove the result unless the underlying studies recorded what students actually did. The intervention, the subject, the learner, the comparison group, study quality and the role the system played all sit inside that one number.
Timing is a second difficulty. Models improve, interfaces change, safeguards are added and users learn new habits, sometimes between a study’s design and its publication. A rigorous result can become historically specific quickly. Social scientists are used to treatments that drift, but generative AI compresses the timetable.
When the question is learning effects, I put little weight on studies that measure exposure only as time spent with a tool or access to it. Those measures cannot distinguish AI replacing an attempt from AI giving feedback after one, or from AI supporting revision. Studies that capture the pattern of use give us a better chance of understanding the mechanism. The same applies to outcomes: exam performance, long-term retention, writing quality, confidence, reasoning and time saved are not interchangeable measures of learning.
For universities and schools, that leaves neither the blanket ban nor the blanket embrace on solid evidential ground. The same issue will turn up outside education. A model can score extremely well on a benchmark and produce a much smaller effect once people reorganise their work around it. The unit worth studying is the working arrangement between a person and a machine.
Elvis Kwame Ofori
Researcher and writer behind EKO Perspectives.
More from EKO Perspectives · Follow via RSS · About the author